"Related content" links (semantic similarity)
What it is
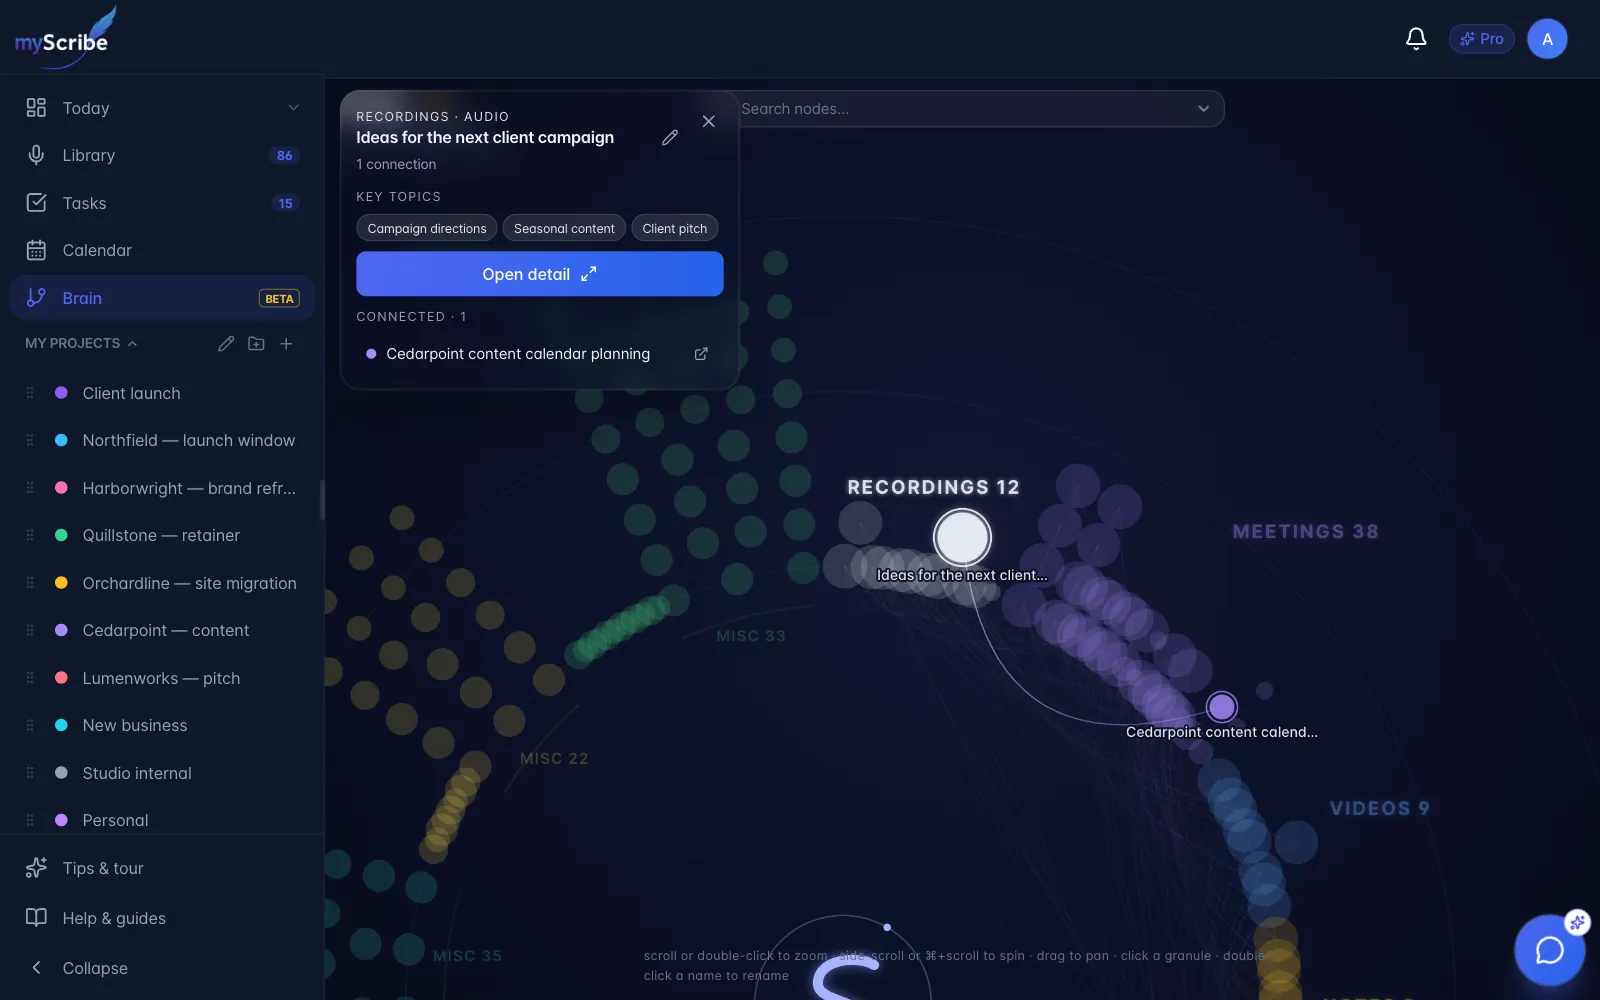
The Memory draws faint threads between two pieces of content that talk about the same thing, even when they share no tag, entity or project. Hovering one shows shared: Related content.
What it actually does
When content is processed, its text is chopped into overlapping chunks and each chunk is converted into a numeric fingerprint (an embedding): the same data the AI chat uses to answer questions about your library. For the graph, each item's five densest chunks are compared against everything else in the workspace, and pairs scoring above a similarity threshold become a thread, capped at 5 related items per item.
Limits and gotchas
- Needs embeddings. Items processed before this existed, or where embedding failed, have no related-content threads. There is no user-visible "re-index" button.
- It's workspace-scoped and quietly degrades. If the lookup fails for any reason, the graph simply draws no related-content threads and says nothing. "The lines disappeared" can just mean a failed background call: reload the page.
- Not a similarity score you can see or tune. The threshold and the 5-per-item cap are fixed; there's no setting.